Get ahead
VMware offers training and certification to turbo-charge your progress.
Learn more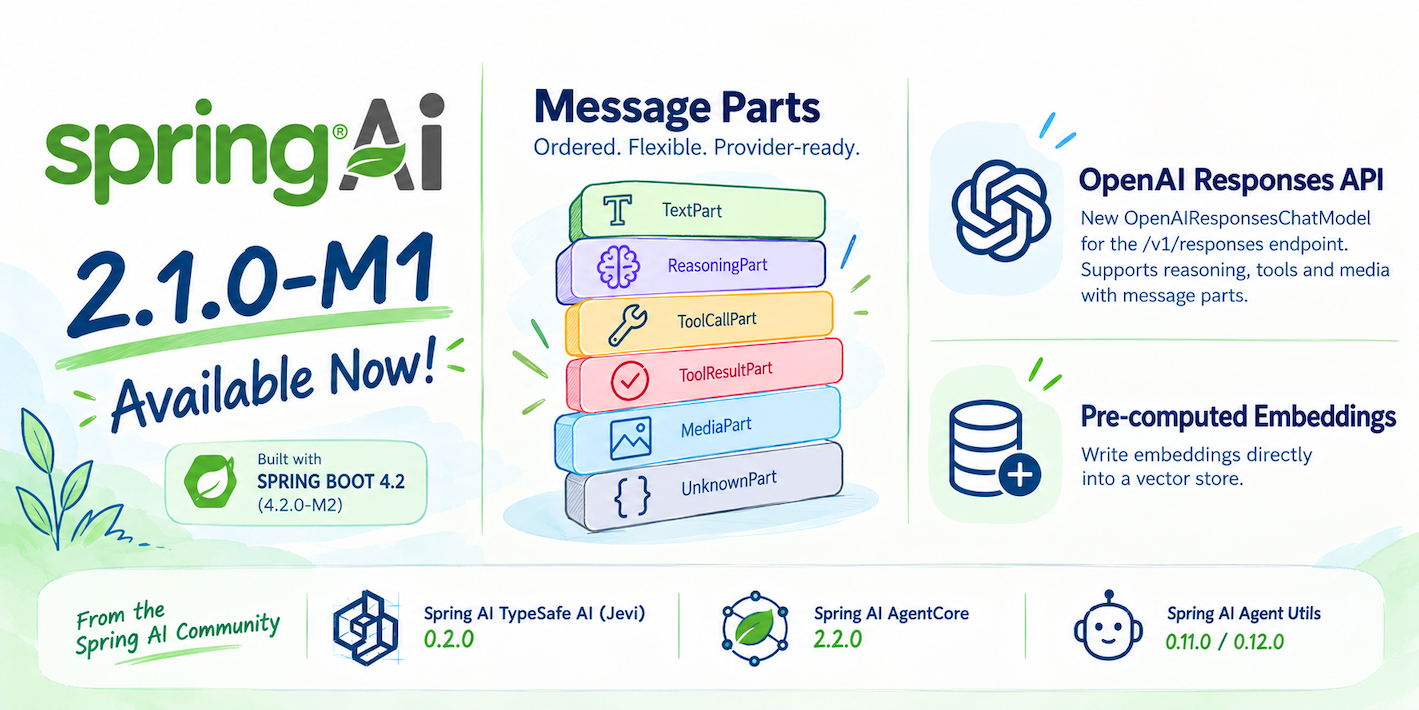
On behalf of the Spring AI team and everyone who has contributed, I'm happy to announce that Spring AI 2.1.0-M1 has been released and is now available from Maven Central!
Release notes | Upgrade notes | Reference documentation
2.1.0-M1 is the first milestone of the 2.1 line. It builds on everything that shipped in 2.0.1, moves the baseline to Spring Boot 4.2 (this milestone is built against 4.2.0-M2), and introduces three new capabilities: initial support for a structured, ordered model for message content, support for the OpenAI Responses API, and a way to write pre-computed embeddings into a vector store.
As with any milestone, the new APIs are ready to try but may still change before GA. Your feedback now is what shapes them.
Message Parts
Until now, a Spring AI message was a text plus side lists of tool calls and media. That shape cannot represent what current models actually return: reasoning interleaved with tool calls, text between images, or provider-specific blocks that must be sent back verbatim on the next turn.
AssistantMessage, UserMessage, and ToolResponseMessage now hold their content as an ordered list of MessagePart entries: TextPart, ReasoningPart, ToolCallPart, ToolResultPart, MediaPart, and UnknownPart. Parts keep the order the provider produced them in, so a conversation round-trips faithfully. A ReasoningPart or ToolCallPart can carry an OpaquePayload, which holds data such as an Anthropic thinking signature or a Gemini thought signature that has to be replayed unchanged. UnknownPart keeps the raw JSON of any block an adapter does not model yet, so nothing is silently dropped.
The familiar accessors (getText(), getMedia(), getToolCalls(), and the new getReasoning()) are now views over the parts, and existing constructors and builders keep producing them in the legacy order. To control the order yourself, add parts directly:
UserMessage question = UserMessage.builder()
    .part(TextPart.of("What changed between these two charts?"))
    .part(MediaPart.of(firstChart))
    .part(MediaPart.of(secondChart))
    .build();

AssistantMessage answer = chatModel.call(new Prompt(question)).getResult().getOutput();
for (ReasoningPart reasoning : answer.getReasoning()) {
    System.out.println("Reasoning: " + reasoning.text());
}
System.out.println(answer.getText());
Streaming models can now deliver a part in increments: chunks carry indexed partial parts and a response id, and MessageAggregator rebuilds the complete parts from them. Subscribers that only read getText() see the same text deltas as before, and tool calls are still buffered and delivered once as a complete call. See the Message Parts section of the reference documentation.
This is initial message part support: only the new
OpenAiResponsesChatModelproduces and consumes parts natively. The otherChatModelimplementations will be refactored to use them in 2.1.0-RC1.
OpenAI Responses API
The new OpenAiResponsesChatModel talks to OpenAI's /v1/responses endpoint, alongside the existing Chat Completions-based OpenAiChatModel. The main reason to use it is correctness: starting with GPT-5.4, Chat Completions does not support tool calling combined with a reasoning effort other than none, while Responses does. If you are building an agent on a current OpenAI flagship model, this is the endpoint to use.
Switching is a single property, and the rest of the spring.ai.openai connection settings stay where they are:
# chat-completions (default) | responses
spring.ai.openai.chat.api=responses
The model is built on message parts. Each item in a Responses reply becomes one part, in order, and the encrypted reasoning content is carried in a ReasoningPart and handed back verbatim across tool calls, so the model keeps its train of thought through a tool loop. OpenAiResponsesChatModel is deliberately stateless: every call sends the whole Prompt, so ChatMemory, advisors, and RAG work exactly as they do with OpenAiChatModel.
OpenAiResponsesChatOptions exposes reasoning effort and reasoning summaries, verbosity, structured output, and image and PDF input. HostedTool enables the tools OpenAI runs on its side: web search, file search, code interpreter, remote MCP, and image generation. Observability and auto-configuration are included. The OpenAI Responses reference page covers the configuration properties and when to pick which endpoint.
Chat memory repositories do not persist message parts yet, so only
InMemoryChatMemoryRepositorypreserves reasoning across conversation turns. The conversation still works with the others, but the model reasons from scratch on each turn. Persistent repository support is planned for 2.1.0-RC1.
Writing pre-computed Embeddings
VectorStore.add() always computes embeddings using the store's own embedding model. Sometimes you already have the vectors: a provider's batch API computed them overnight at a discount, another team owns the embedding pipeline, a multimodal model embedded an image, or you are migrating from a system that exports text and vectors together.
The new VectorStore.upsert() takes an EmbeddedDocument, pairing a Document with its float[] vector, and stores the vector as given:
float[] embedding = ...; // computed elsewhere
Document document = new Document("8f14e45f-ceea-467a-9a3e-5b1c2d6f7a90", "some text",
        Map.of("source", "manual"));

vectorStore.upsert(List.of(new EmbeddedDocument(document, embedding)));
As the name says, writing the same id again replaces the row, so an ingestion job with stable ids can be re-run safely after a failure. Every batch is checked against the index width before anything is written. pgvector, Redis, Elasticsearch, and Qdrant support upsert in this milestone; other stores throw until they opt in. A new DocumentMetadata.CONTENT_REF key lets you point to content kept outside the store, for rows whose vector came from an image or a file too large to inline. See Writing User-Supplied Embeddings.
Smaller additions
McpStatelessSyncServerCustomizer and McpStatelessAsyncServerCustomizer beans, mirroring the customizers the stateful servers already had. Previously, you had to exclude and re-declare the whole server bean.Long instead of failing with a NumberFormatException.spring.ai.openai.timeout and spring.ai.openai.chat.timeout are honored again. Since 2.0.1, every request carried a 60-second per-call timeout that overrode the configured value, which aborted streaming turns longer than a minute with OpenAIIoException: Stream failed.additionalProperties: false at every object level. This fixes strict mode for schemas that do not come from Spring AI's own generator, such as MCP tool schemas or hand-written input schemas.TextReader closes the resource stream it reads from, instead of leaking a file descriptor per document.InMemoryChatMemoryRepository copies the message list on save, so later changes to the caller's list no longer alter the stored conversation.MariaDBVectorStore schema validation works when no schema name is configured, rather than reporting an existing table as missing from schema null.The MCP client documentation gained a section on client scope and session boundaries (what the auto-configured beans share, and how to get per-user isolation when you need it), and the guidance on MCP and local tool name collisions was refined. The OpenAI reasoning effort property is now documented.
Spring AI now tracks Spring Boot 4.2, and the Anthropic Java SDK moves to 2.64.0. The build is now configured for reproducible builds, and tests that assumed Unix line endings were fixed so the project builds on Windows.
Thank you to everyone who worked on this release:
@CryoThrust, @JamesBLewis, @Lubaoshuai, @chabinhwang, @chensishang, @dimitarproynov, @dlwldn30, @fatan, @herder, @ilayaperumalg, @jhpark1227, @kezhenxu94, @martin-grofcik, @pengmoubuaixuexi, @sdeleuze, @sobychacko, and @tzolov
JevChatModel. See the reference documentation.401 response for a missing API key, and issuer URL validation in the CIMD flow.ExecBackend with a Docker backend for sandboxed command execution, a Workspace abstraction, directory confinement for the search tools, and InterruptAdvisor and ToolCallListener for controlling the agent loop.appendEvent idempotent, add keyword and pattern search across sessions through CrossSessionRecallTools, and stop duplicated prompt history when the memory advisor runs inside a tool-calling loop.Work on 2.1.0-RC1 has started. Message parts are the foundation for most of it:
ChatModel implementations to produce and consume MessagePart content natively, while preserving backward compatibility for code that uses the current accessors.SessionRepository implementations will persist the full MessagePart structure. Reasoning will then survive across conversation turns with persistent storage too, not only with the in-memory repository.Try the milestone in an existing application, or start a new one on start.spring.io. The message parts model and the Responses API are exactly the kind of changes we want feedback on before GA — open an issue if something is broken, or start a discussion to tell us what you would like to see next.
Cheers!

VMware offers training and certification to turbo-charge your progress.
Learn moreTanzu Spring offers support and binaries for OpenJDK™, Spring, and Apache Tomcat® in one simple subscription.
Learn moreCheck out all the upcoming events in the Spring community.
View all